Generative Models
Auto-regressive model, GAN으로 가기 위한 관문
머신러닝, 딥러닝에서 의미하는 Generative model이 무엇인지, 이를 이해하기 위한 기본적인 통계 이론, 다양한 Generative model의 아이디어, 구조에 대해 배웁니다. 수식적으로 어려움이 있을 수 있습니다.
Introduction
Richard Feynman
“What i cannot create, I do not understand”
Generative model은 단순히 이미지를 만들고 텍스트를 생성하는 것만의 의미를 갖지 않는다.
Learning a Generative model
Suppose we are give images of dogs.
We want to learn a probability distribution such that
- Generation : If we sample should look like a dog(
sampling) - Density estimation : should be high if looks like a dog, and low otherwise(
anomaly detection)- Also known as,
explicit(명백한) models - 입력이 주어졌을 때, 원하는 이미지가 ‘아닌’ 것을 판단할 수 있는.
- 엄밀한 의미에서는 Generative model은 Discriminator를 포함하고 있다.
- Also known as,
- Unsupervised representation learning : We should be able to learn what these images have in common, e.g., ears, tail, etc(
feature learning)
Then, how can we represent ??
Basic Discrete Distributions
- Bernoulli distribution : coin flip
- D = {Heads, Tails}
- Specify . Then .
- Write : Ber()
- Categorical distribution : m-sided die
- D = {1, , m}
- Specify , such that =1.
- Write : Cat()
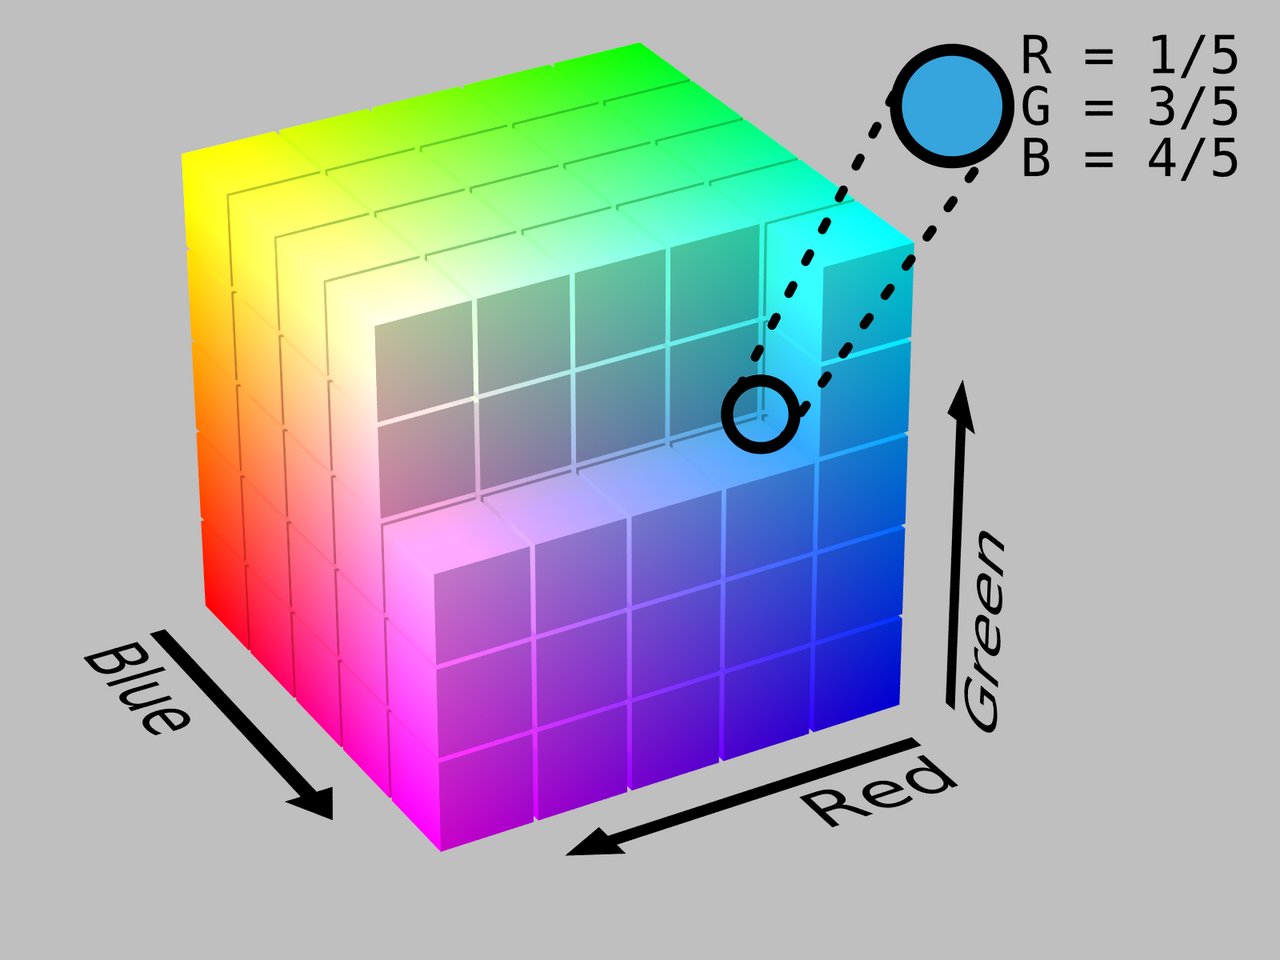
Example 1
Modeling an RGB joint distribution (of a single pixel)
- Number of cases?
- 256 X 256 X 256
- How many parameters do we need to specify?
- 255 X 255 X 255
Example 2 - mnist
Suppose we have of binary pixels (a binary image).
How many possible states?
Sampling from generates an image.
How many parameters to specify ?
어쨌든, 파라미터의 수가 많을 수록 점점 학습은 어려워지는 것이 통상적 이론!
Structure Through Independence
파라미터를 줄이고자 시작한 가정 : 모든 픽셀이 서로 independent 하다면?
-
What if are independent, then
-
How many possible states? :
-
How many parameters to specify ? :
-
entires can be described by just numbers! But this independence assumption is too strong to model useful distributions.
결과적으로 픽셀을을 서로 독립하다고 가정한다면, 개의 파라미터가 개로 줄어든다는 점은 엄청난 빅이득이다.
Conditional Independence
따라서 이 두 파라미터의 중간 어딘가의 파라미터 수를 가진 distribution을 만들기 위한 몇 가지 트릭을 사용한다.
- Three important rules
-
Chain rule :
-
Bayes’ rule:
-
Conditional independence:
- If , then
- 만약 가 주어졌을 때, 와 가 independent 하다면, then 를 표현함에 있어 는 상관이 없으므로 given 일 때, 와 상관없이 의 확률로만 표현 가능하다.
-
위의 Chain Rule에서 각 파라미터의 수를 계산해보면
- : 1 parameter
- : 2 parameter (one per and one per )
- : 4 parameter
- Hence, , which is the same as before.
왜 파라미터 갯수가 같을까?
- 결론적으로 아무것도 달라진게 없기 때문이다.
- now, suppose , is called Markov assumption, then
- 위의 식 (1)이 식 (2)와 같은 이유는 독립적이라는 가정때문이다.
- How many parameters?
- Hence, by leveraging the Markov assumption, we get exponential reduction on the number of parameters.
- Auto-regressive models leverages this
conditional independency.
Auto-regressive Model
- Suppose we have 28 by 28 binary pixels.
- Our goal is to learn over
- How can we parametrize ?
- Chain rule을 사용하여 결합확률분포(joint distribution)의 인자로 나타내면
- This is called an
autoregressive model:- 즉, autoregressor 모델은 바로 직전 뿐만아니라 이전의 모든 픽셀(데이터)이 dependent 한 것도 autoregressive model이라고 한다.
- Note that we need
an orderingof all random variables.- 픽셀값에 순서를 매겨야할 필요성이 있다.
- 어떤식으로 conditional independency를 주느냐에 따라서 전체 스트럭쳐가 달라진다.
- 방금 우리의 예제는 markov assumption이었다. joint distribution을 어떻게 쪼개느냐가 중요
NADE : Neural Autoregressive Density Estimator
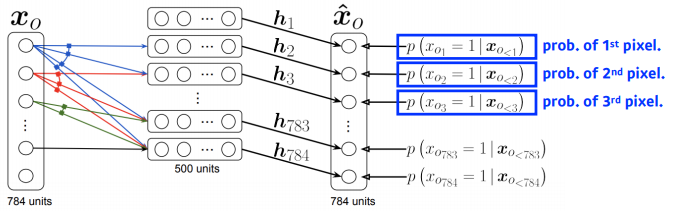
-
the probability distribution of i-th pixel is
- where
-
i번째 픽셀을 첫번째부터 i-1번째 픽셀에 dependent 하게 한다
-
neural network 입장에서는 입력차원이 계속 변한다
- 그래서 weight가 계속 커진다.
- 즉 3번째 픽셀에 대한 확률분포를 만들때는 1번째와 2번째 총 2개의 입력을 받는 weight가 필요한 반면
- 100번째 필섹에 대한 확률분포를 만들때는 99개의 입력을 받는 weight가 필요하다.
-
NADE is an explicit model that can compute the density of the given inputs
- 단순히 generate만할 수 있는 것이 아니라 임의의 784개의 binary vector가 주어지면 이에 대한 확률을 계산할 수 있다
- how about implicit?
- 당연히 반대로 generate만 할 수 있는 모델을 의미한다. (확률 계산 불가능!)
-
how can we compute the density of the given images?
- suppose we have a binary image with 784 binary pixels,
- then, the joint probability is computed by
- where each conditional probability is computed independently
-
In case of modeling continuous random variables, a mixture of Gaussian can be used
조만간에논문리뷰를 진행해야겠다.
Pixel RNN
이미지의 픽셀을 만들고 싶은 모델임
- We cal alse use RNNs to define an auto-regressive model.
- For example, for an RGB image,
- : Prob. i-th R
- : Prob. i-th G
- : Prob. i-th B
- 차이점
- 앞에서는 fc-layer를 통해서 만들었다.
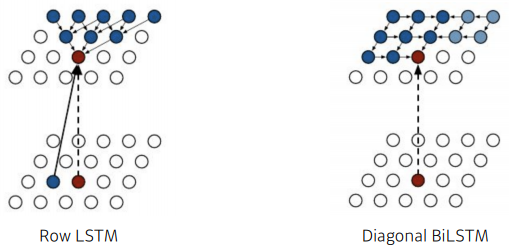
- RNN을 통해서 generate 했다는 점이 차이점이 있다. 그 중에서 다시 두 가지 방식으로 ordering하는 방식이 나뉘게 된다.
- RowLSTM
- Diagonal BiLSTM
이어서 다음
포스팅에서는 VAE를 비롯한 variational model과 대표적 생성모델 GAN에 대한 내용이 이어집니다.