Generative Models2
GAN을 공부하려다 VAE를 깨달아버렸다...
지난 강의에서는 Auto-regressive model의 Generative model에 대해 배웠습니다. Generative models part 2 에서는 실제로 많이 다뤄지는 Practical 한 Generative model인 Variational Auto Encoder와 Generative Adversarial Network 를 이용하여 Latent variable model 에 대해 배웁니다.
Latent Variable Models
Variational autoencoder를 만들었고, Adam optimizer를 만들기도 한 D.Kingma의 Ph.D. Thesis인
“Variational Inferene and Deep Learning: A New Synthesis”를 꼭 읽어보길 바란다.
Question : “Is an autoencoder a generative model?”
Answer : “No!”
많은 사람들이 VAE를 generative model인 것을 알고 있기 때문에, AE도 generative model이라고 생각하겠지만 그렇지 않다.
VAE가 AE와는 다르게 generative model이 될 수 있는 이유가 무엇인지를 아는 것이 이번 포스팅의 핵심이다.
Variational Auto-encoder
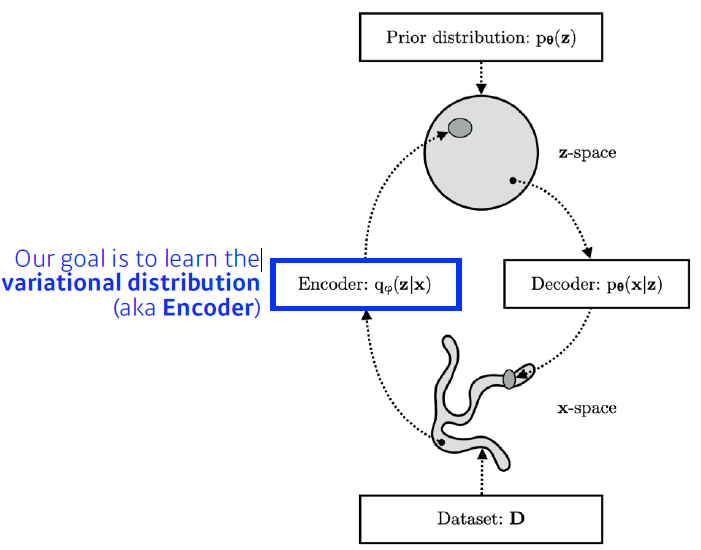
Variational inferene (VI)
- The goal of VI is to optimize the
variational distributionthat best matches theposterior distribution- Posterior distribution(사후 확률) :
- VI의 목적은 이 posterior distribution을 찾는데에 있다.
- 여기서 와 가 바뀐 확률 분포를 Likelihood라 부른다.
- 즉, 관찰값(observation) 가 주어졌을 때, 관심있어하는 random variable()의 확률 분포 의 확률 분포를 말한다. 여기서 는
latent vector가 된다.
- Variational distribution :
- 일반적으로 posterior distribution을 계산하기 힘든 경우가 많다.
- 따라서 내가 학습가능한, 최적화시킬 수 있는 무언가로 근사하는 것이 목적이고, 그 근사한 분포가 Variational distribution이다.
- 즉, 다시 말하면 VI의 목표는 posterior 분포를 가장 잘 근사할 수 있는 Variational distribution을 찾는 과정이다.
- Posterior distribution(사후 확률) :
- In particular, we want to find the variational distribution that minimizes the KL divergence between the true posterior
Kullback-Leibler divergence
-
더 나아가기 앞서 KL-Divergence를 복습해보자. Kullback-Leibler divergence는 두 확률 분포의 다름의 정도(=relative entropy)를 의미한다.
-
KL-Divergence는 두 분포간의 거리(distance)는 아니지만, 비슷(?)한 개념이라고 할 수 있다.
-
거리와 상이하다고 하는 이유는 commutative하지 않기 때문이다.
-
아무튼 KL-Divergence를 수식으로 나타내면 다음과 같다.
-
이때, 만일 두 분포 와 가 정규분포(Gaussian Distribution), 을 따를 경우 다음과 같이 유도가 가능하다.
-
이 식은 ELBO의 마지막 부분에서 다시 쓰일 예정이다.
ELBO
- posterior distribution이 뭔지도 모르는데, variational distribution을 찾는다는 것 자체가 어불성설이다.
- 이것을 가능하게 해주는 방법이 Variational Inference의 ELBO 트릭이다.
ELBO(Evidence lower Bound):- 위 식에서 우리의 목표는
Objective term을 감소시키는 것이다. Variational distribution과 posterior distribution의 KL-Divergence를 감소시키는 것이, 두 분포의 ‘다름의 정도’를 줄이는 것이고 근사시킨다는 의미이기 때문이다. - 하지만, 이는 계산하기 힘든 경우가 대다수이고, 그 과정 또한 어렵다.
- 그러므로 좌측의
ELBO term을 증가시킴으로써 간접적으로 objective term을 감소시키는 trick을 사용한다.
- **Reconstruction Term** : This term minimizes the reconstruction loss of an auto-enoder.
	**Prior Fitting Term** : This term enfores the latent distribution to be similar to the prior distbution
- 이때, 앞서 `식(1)`에서 유도했듯이, KL-Divergence는 두 확률분포가 정규분포라고 가정했을 때, 간단하게 계산이 가능하다. 이 의미는 단순히 **계산**이 가능함을 의미하기보다는 **고정된** 값을 의미한다는 것이다.
- 즉, 이 의미는 결국 `ELBO Term`을 증가시키기 위해서 Reconstruction Term을 통해 계산할 수 있음을 의미한다.
- 그렇다면, $$\underbrace{\mathbb{E}_{q_\phi(z\vert x)}\left[p_\theta(x\vert z)\right]}_\text{Reconstruction Term}$$의 의미를 살펴보자.
- $x$가 주어졌을 때, $z$가 encoder의 결과로 얻어진 분포를 따르고, 이때 다시 $z$일때 샘플 $x$가 생성될 확률의 기대값이 reconstruction term이 의미하는 바이고, 이를 **최대화**해야하는 것이 우리의 목적이므로, 이는 곧 MLE(Maximum likelihood estimation)이라고 할 수 있다.
- 또한, 이는 Cross-entropy로 표현이 가능하다.
> - 참고로 evidence lower bound의 이름에 lower bound가 들어가는 이유는 **ELBO term = Reconstruction Term - <u>Prior fitting term</u>**의 식에서  KL-Divergence로 이루어진 <u>Prior fitting term</u>은 항상 양수이기 때문이다.
> - 때문에, **ELBO term** $\geq$**Reconstruction Term** 임을 의미한다. - 결론적으로, Reconstruction term은 라는 입력을 encoder를 통해 latent space로 보냈다가 다시 decoder로 돌아오는 reconstruction loss를 줄이는 것이 Reconstruction Term이고,
- 라는 인풋 데이터를 latent space로 올려 점들이 되었을 때, 이 점들이 이루는 분포(Posterior distribution)가 내가 가정하는 latent space의 prior distribution(사전 분포)와 비슷하게 만들어지게 하는 것을 의미하는 term이 Prior fitting Term이다.
- 이러한 이유로 VAE는 Generative model이지만, 엄밀한 의미에서는 implicit model이다.
Key limitation:
-
It is an intractable model (hard to evaluate likelihood)
-
The prior fitting term must be differentiable, hence it is hard to use diverse latent prior distributions.
-
In most cases, we use an isotropic Gaussian.
Isotropic Gaussian: 모든 output dimension이 independent한 가우시안 분포를 의미한다.
Adversarial Auto-encoder
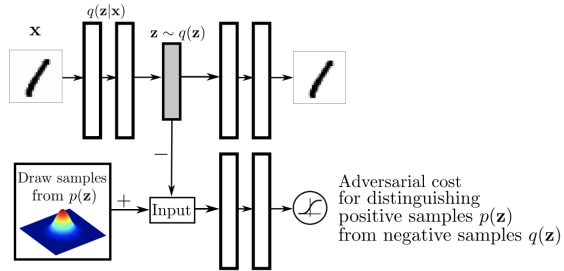
- It allows us to use any arbitrary latent distributions that we can sample.
Generative Adversarial Network
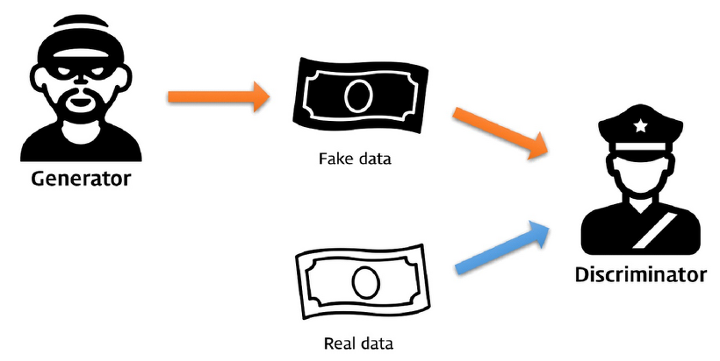
- 도둑(Generator)은 위조지폐를 만든다.
- 경찰(Discriminator)은 가지고 있는 ‘진짜’지폐와 ‘위조’지폐를 비교해서 진짜와 가짜를 구분한다
- 그걸 바탕으로 다시 도둑은 위조지폐를 만든다.
- 반복한다.
GAN vs. VAE
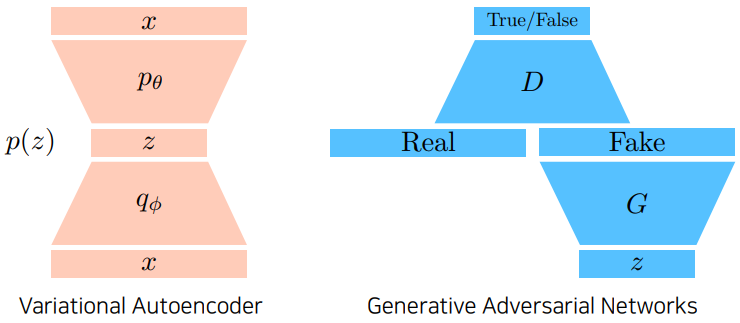
- VAE와 GAN의 차이는 위의 그림과 같다.
GAN Objective
-
A two player minimax game between
generatoranddiscriminator. -
For discriminator:
- where the optimal discriminator is
- 여기서 optimal discriminator는 Generator가 fix가 되어있다고 가정했을 때, 항상 최적으로 분류를 해주는 Discriminator를 의미한다.
-
For generator :
- Plugging in the optimal discriminator, we get
여러 종류의 GAN
DCGAN
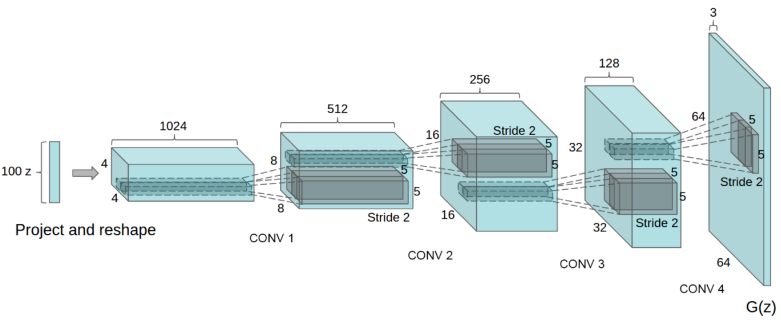
- GAN과의 차이점은 단순 Dense layer를 사용했는지, Conv, Deconv layer를 사용했는지의 차이다.
Info-GAN
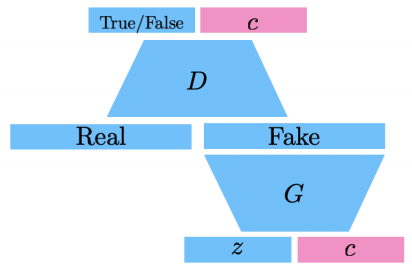
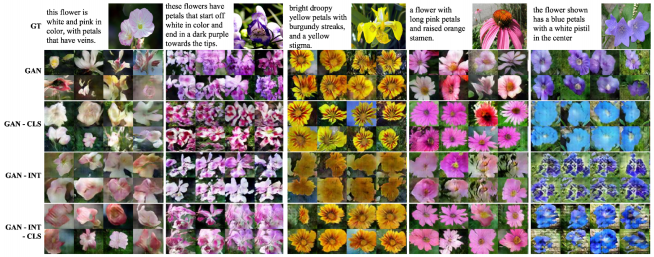
Text2Image
Puzzle-GAN
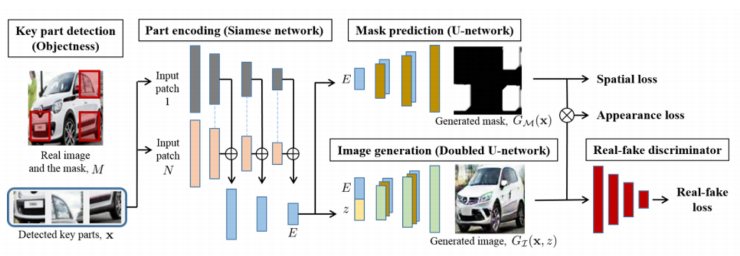
- 간단한 설명을 추가하자면, 이미지 내의 subpatch들을 복원하는 모델이다.
CycleGAN
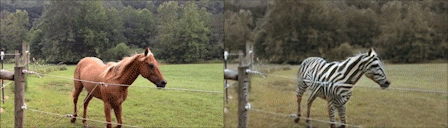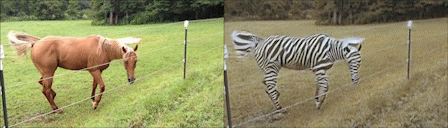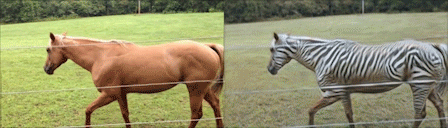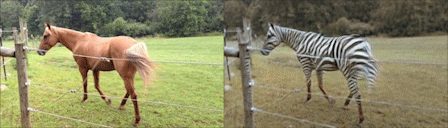
- Cycle - consistency loss : 도메인을 바꾸기 위한 loss 정의 방식인데 매우 중요하다.
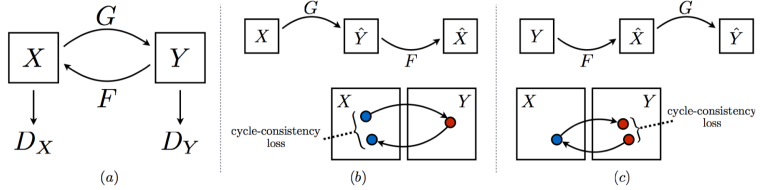
- GAN 구조가 두개 들어간다.
Star-GAN
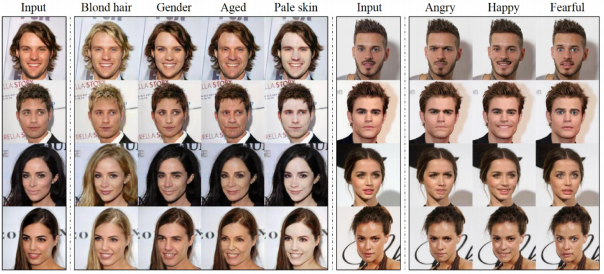
- 단순히 생성하는 것 뿐만아니라 Input 이미지를 지정한 형태로 바꿀 수 있고, 최근에도 활발한 후속 논문이 발표되고 있다.
Progressive-GAN

-
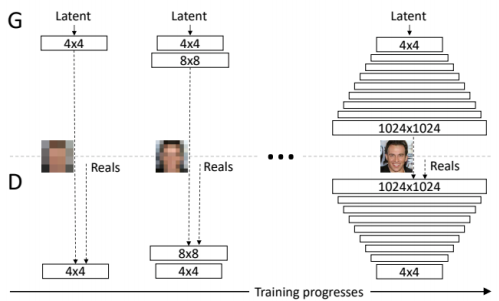
Key Ideas:
모델이 한번에 고해상도의 이미지를 만드는 것은 매우 어렵기 때문에, 점차적으로 차원을 늘려가면서 생성한다.
Further Reading