NLP / NaiveBayes and Embedding
NLP를 시작해보자
자연어 처리의 첫 시간으로 NLP에 대해 짧게 소개하고 자연어를 처리하는 가장 간단한 모델 중 하나인 Bag-of-Words를 소개합니다. Bag-of-Words는 단어의 표현에 있어서 one-hot-encoding을 이용하며, 단어의 등장 순서를 고려하지 않는 아주 간단한 방법 중 하나입니다. 간단한 모델이지만 많은 자연어 처리 task에서 효과적으로 동작하는 알고리즘 중 하나입니다. 그리고, 이 Bag-of-Words를 이용해 문서를 분류하는 Naive Bayes Classifier에 대해서 설명합니다. 이번 강의에서는 단어를 벡터로 표현하는 방법, 문서를 벡터로 표현하는 방법에 대해 고민해보면서 강의를 들어주시면 감사하겠습니다.
1. Intro to NLP, Bag-of-Words
Intro to Natural Language Processing(NLP)
이번 과정의 목표
- Natural language processing (NLP), which aims at properly understanding and generating human languages(NLG), emerges as a crucial application of artificial intelligence, with the advancements of deep neural networks.
- This course will cover various deep learning approaches as well as their applications such as language modeling, machine translation, question answering, document classification, and dialog systems.
학문적 체계
- NLP(주요 학회 : ACL, EMNLP, NAACL)
- low level parsing
- 토크나이징, stemming(어미의 변화에 대한 연구, 어근 추출)
- word and phrase level
- 개체명 인식(NER) : 단일 단어 혹은 여러 단어로 이루어진 고유명사를 인식하는 작업
- POS(part-of-speech) tagging : 문장내에서 워드의 품사나 성분이 무엇인지 알아내는 task
- noun-phrase chunking
- dependecy 파싱
- coreference resolution
- Sentence level
- 감정분석(sentiment analysis)
- machine translation
- Multi-sentence and paragraph level
- Entailment prediction : 두 문장간의 논리적 내포 및 모순관계 추론
- question answering : 독해 기반의 질의응답
- dialog systems : 대화모델, 챗봇임.
- summarization
- low level parsing
- Text mining(KDD, The webconf(formerly, WWW), WSDM, CIKM, IWSM)
- 빅데이터와 연관된 경우가 많다.
- Extract useful information and insights from text and document data
- Document clustering (e.g., topic modeling)
- Highly related to computational social science - 트위터나 소셜 미디어를 분석하여 사회현상 등등을 분석하는데 사용된다.
- Information retrieval - 정보검색 분야 (주요 학회 : SIGIR, WSDM, CIKM, RecSys)
- Highly related to computational social science
- 이미 검색 시스템이 고도화 되어 상대적으로 연구가 더딘 분야이다.
- 하지만, 추천시스템 분야는 활발히 연구되고 있다.
- Highly related to computational social science
NLP 분야의 트렌드
- 단어를 벡터로 나타내는 테크닉 w2v or glove
- RNN 계열의 모델
- attention module에 기반한 transformer 모델
- 각 NLP task에 맞는 세부적인 모델 설계로 분화됨
- self-supervised 학습된 모델들(bert, gpt-3)은 특정 태스크에서 벗어나 다양한 태스크를 수행하는 모델로 발전하였다.
- 모델이 커짐으로 인한 자원적 한계로 전이학습이 트렌드가됨
Bag of Words
Bag-of-Words Representation
-
Step 1. 유니크한 단어를 모아서 vocab을 구축한다.
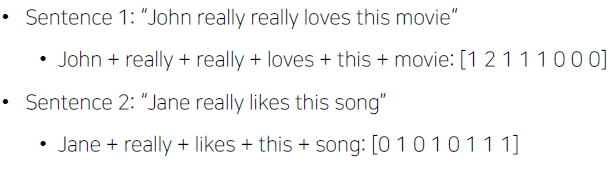
- Example sentences: “John really really loves this movie“, “Jane really likes this song”
- Vocabulary: {“John“, “really“, “loves“, “this“, “movie“, “Jane“, “likes“, “song”}
-
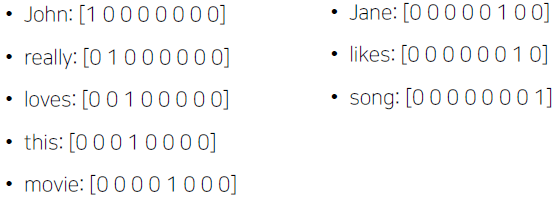
Step 2. 각 단어를 one-hot 벡터로 표현한다.
-
Vocabulary: {“John“, “really“, “loves“, “this“, “movie“, “Jane“, “likes“, “song”}
-
임의의 두 단어쌍의 유클리디언 distance는 이고, 코사인 유사도는 모두 0이다
-
즉, 단어의 의미와 상관없이 모두 동일하게 설정된다.
-
-
문장/문서는 이러한 one-hot 벡터들의 합으로 나타낼 수 있다.
NaiveBayes Classifier for Document Classification
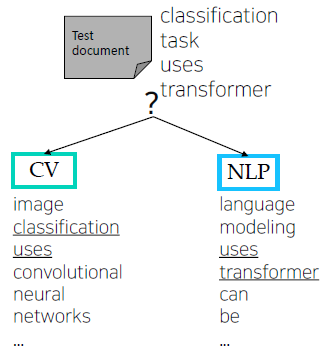
위와 같이 Bag of Words 벡터로 나타낸 문서를 정해진 카테고리 혹은 클래스로 분류할 수 있는 대표적인 방법인 NaiveBayes Classifier를 알아보자
-
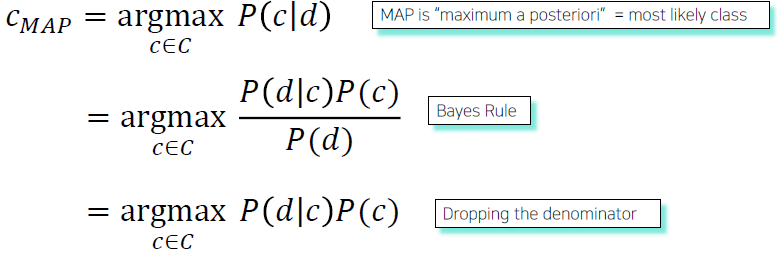
Bayes’ Rule Applied to Documents and Classes
-
For a document d and a class c
-
For a document
d, which consists of a sequence of wordsw, and a classc -
The probability of a document can be represented by multiplying the probability of each word appearing
-
-
특정 카테고리 c가 고정되었을 때, 문서 d가 나타날 확률이고, 이는 부터 까지 동시에 나타날 동시사건으로 볼 수 있다. 각 단어가 등장할 확률이 서로 독립이면, 이를 곱한 형태로 나타낼 수 있다.
-
-
Example
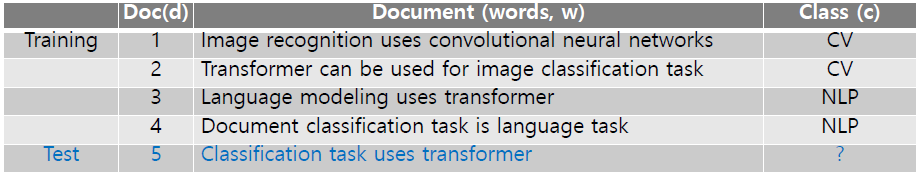
이러한 상황에서 Test 데이터의 Classification task usses transformer라는 문장의 각 단어에 대한 조건부 확률은 다음과 같다.
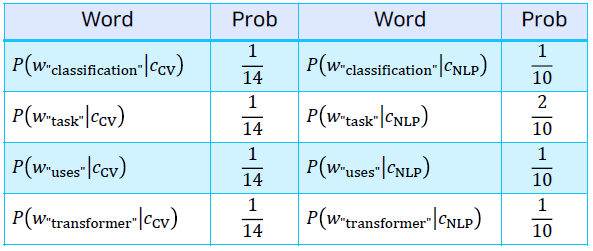
For a test document = “Classification task uses transformer”
- We calculate the conditional probability of the document for each class
- We can choose a class that has the highest probability for the document
-
이다.
2. Word Embedding
단어를 벡터로 표현하는 또 다른 방법인 Word2Vec과 GloVe를 소개합니다.
Word2Vec과 GloVe는 최근까지도 자주 사용되고 있는 word embedding 방법입니다. Word2Vec과 GloVe는 하나의 차원에 단어의 모든 의미를 표현하는 one-hot-encoding과 달리 단어의 distributed representation을 학습하고자 고안된 모델입니다. Word2Vec과 GloVe가 단어를 학습하는 원리를 중심으로 강의를 들어주시면 감사하겠습니다
Further Reading
Further Questions
- Word2Vec과 GloVe 알고리즘이 가지고 있는 단점은 무엇일까요?
What is Word Embedding?
- Express a word as a vector
- ‘cat’ and ‘kitty’ are similar words, so they have similar vector representations short distance
- ‘hamburger’ is not similar with ‘cat’ or ‘kitty’, so they have different vector representations far distance
- 기본 아이디어는 비슷한 의미의 단어가 벡터 공간 상에서 가까운 곳에 위치하게끔 부여하는 것에 있다.
Word2Vec
- 인접 단어를 기준으로 문맥의 단어 벡터를 학습한다.
- 가정 : 비슷한 맥락의 단어는 의미가 비슷하다.
Word2Vec의 Idea
한 단어가 주변에 등장하는 단어들을 통해 그 의미를 알 수있다는 가정에 착안하므로, 주어진 학습 데이터를 바탕으로 원하는 단어의 주변 확률 분포를 예측하게 된다.
- Distributional Hypothesis: The meaning of “cat” is captured by the probability distribution
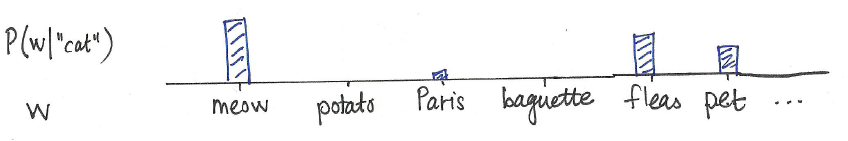
- 위와 같이 ‘Cat’이라는 단어 주위에 “meow”, “Pet” 등의 단어가 높은 확률로 등장한다는 것을 학습한다.
How Word2Vec Algorithm Works
-
Sentence : “I study math.”을 생각해보자
-
토크나이징을 통해 Vocabulary: {“I”, “study” “math”}으로 사전을 구축한다.
-
사전의 사이즈만큼의 dimension을 가지는 one-hot-vector로 vocab을 표현한다.
-
이후 Sliding Window라는 기법을 통해 중심단어를 기준으로 앞/뒤 단어를 나타내는 pair를 표현한다.
-
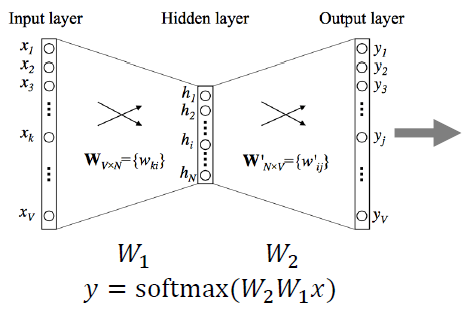
vocab 사이즈가 이 경우 3이므로 입출력 노드 수는 3개로 되고, 히든 레이어의 노드 수는 사용자가 지정한다. 사영되는 벡터공간의 dimension과 같은 크기를 지닌다.
-
Hidden layer의 차원을 2차원이라고 가정하자.
-
Input node to Hidden layer를 표현하는 는 3차원에서 2차원으로 표현되고, 다시 ouput layer로 간는 는 2차원에서 3차원으로 표현되므로 아래와 같이 표현할 수 있다.
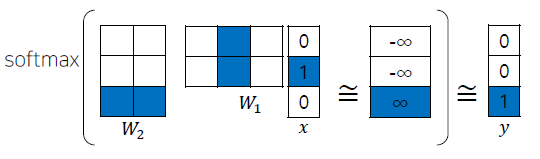
-
[0, 1, 0]로 표현되는 단어 “study” 가 input, [0, 0, 1]로 표현되는 단어 “math” 가 target vector라고 할 때, 위와 같이 학습할 수 있다.
Property of Word2Vec
-
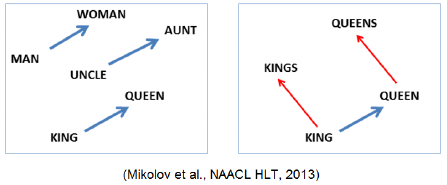
The word vector, or the relationship between vector points in space, represents the relationship between the words.
-
The same relationship is represented as the same vectors.
-
벡터간의 연산이 단어간의 유사도를 반영하여 표현되는 것이 특징이다.
Property of Word2Vec – Intrusion Detection
Word2Vec을 통해서 할 수 있는 또 다른 Task중 하나 : intrusion detection
- 여러 단어들이 주어졌을 때, 나머지 단어와 그 의미가 가장 상이한 단어를 찾는 task
- 단어별로 나머지 단어와의 euclidean distance를 계산하고 평균값을 계산하여 차이를 발견한다.
Application of Word2Vec
NLP task에 Word2Vec을 이용한 다양한 응용이 이뤄지고 있다.
- Word similarity
- Machine translation
- Part-of-speech (PoS) tagging
- Named entity recognition (NER)
- Sentiment analysis
- Clustering
- Semantic lexicon building
Glove
각 입력, 출력 단어 쌍에 대하여, 학습 데이터에서 두 단어가 한 윈도우에서 동시에 몇 번 등장했는지를 사전에 계산하고, 입력워드의 임베딩벡터간의 내적값이 두 단어가 한 윈도우 내에서 몇 번 ‘동시에’ 나타났는가, 그 값에 로그를 취해 fitting 될 수 있도록 학습하는 방식이다.
- Rather than going through each pair of an input and an output words, it first computes the co-occurrence matrix, to avoid training on identical word pairs repetitively.
- Afterwards, it performs matrix decomposition on this co-occurrent matrix.
Word2Vec: 특정한 입출력 단어 쌍이 자주 등장했을 때, 이 같은 데이터 아이템이 여러번에 학습 됨으로써 두 워드 임베딩 내적값이 빈번해지면서 커지는 방식이라면
Glove : 애초에 동시에 등장하는 단어 쌍이 동시에 등장하는 횟수를 미리 계산하고 이에대한 로그값을 취한 그 값을 직접 해당 두 단어간의 내적값과 얼마나 차이나는지를 loss로 하여 학습한다. 따라서 중복되는 계산을 줄여주는 점에서 빠르고, 적은 데이터에 대해서도 잘 동작하는 특성을 지닌다.
Linear Substructure
Glove에서도 Word2Vec의 Linear Substructure의 결과처럼 벡터에 따른 word간의 차이가 유사하게 적용됨을 볼 수 있다.